Google DeepMind · launched 19 Feb 2026
Gemini 3.1 Pro
Preview
Google's publicly available Pro model for complex reasoning, multimodal understanding and agentic coding, currently in preview.
Read the official announcement- Vendor
- Google DeepMind
- Launch date
- 19 Feb 2026
- Input price
- $2.00 / 1M tokens
- Output price
- $12 / 1M tokens
- Cached input
- $0.20 / 1M tokens
- Batch discount
- 50%
- Context window
- 1.05M tokens
- Max output
- 66K tokens
- Input types
- Text, Image, Video, Audio, PDF
- API model ID
- gemini-3.1-pro-preview
- Availability
- Preview
Rates apply to prompts up to 200K tokens. Above 200K, input is $4, output $18 and cached input $0.40 per million tokens. Cache storage and grounding are billed separately.
Official pricing source · checked 8 Oct 2026
Price compared with other models
| Model | Launched | Input / 1M | Output / 1M | Cached / 1M | Blended / 1M | vs Gemini 3.1 Pro |
|---|---|---|---|---|---|---|
| Claude Haiku 5.5AnthropicListed prices and comparisons apply to prompts up to 100K tokens. Above 100K, input costs $0.50, output $2.50 and cache reads $0.05 per million tokens. | 7 Oct 2026 | $0.10 | $0.50 | $0.01 | $0.20 | 96% cheaper |
| GPT-6 LunaOpenAI | 22 Sept 2026 | $0.10 | $0.50 | $0.01 | $0.20 | 96% cheaper |
| GPT-5.6 LunaOpenAI | 9 Jul 2026 | $0.20 | $1.20 | $0.02 | $0.45 | 90% cheaper |
| Gemini 3.5 Flash-LiteGoogle DeepMindText, image, video and audio inputs share the listed rate. Cache storage and grounding are billed separately. | 21 Jul 2026 | $0.30 | $2.50 | $0.03 | $0.85 | 81% cheaper |
| Gemini 3.8 FlashGoogle DeepMindIntroductory rates through 31 December 2026. From 1 January 2027, input is $1.50, output $7.50 and cached input $0.15 per million tokens. Cache storage and grounding are billed separately. | 2 Sept 2026 | $0.75 | $3.75 | $0.075 | $1.50 | 67% cheaper |
| Claude Haiku 4.5Anthropic | 15 Oct 2025 | $1.00 | $5.00 | $0.10 | $2.00 | 56% cheaper |
| Grok 4.7SpaceXAIBase rates apply up to 200K context tokens; higher-context requests use different rates. Batch API is not supported. The separate fast variant costs twice as much. | 21 Sept 2026 | $2.00 | $6.00 | $0.50 | $3.00 | 33% cheaper |
| Claude Sonnet 5Anthropic | 30 Jun 2026 | $2.00 | $10 | $0.20 | $4.00 | 11% cheaper |
| Claude Sonnet 5.5AnthropicCache reads were reduced from $0.20 to $0.10 per million tokens on 7 October 2026. | 28 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 | 11% cheaper |
| Gemini 4 ArgonGoogle DeepMind · Limited accessAnnounced introductory rates for the upcoming broader launch. Regular rates will be $4 input and $20 output per million tokens; the introductory end date and batch discount are not published. | 30 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 | 11% cheaper |
| GPT-6 SolOpenAIListed rates apply up to 272K input tokens. Above 272K, input costs $4, cached input $0.40 and output $15 per million tokens for the full request. | 22 Sept 2026 | $2.00 | $10 | $0.20 | $4.00 | 11% cheaper |
| GPT-6.1 SolOpenAIListed rates apply up to 272K input tokens. Above 272K, input costs $4, cached input $0.20 and output $15 per million tokens for the full request. | 29 Sept 2026 | $2.00 | $10 | $0.10 | $4.00 | 11% cheaper |
| Gemini 3.1 ProGoogle DeepMind · PreviewRates apply to prompts up to 200K tokens. Above 200K, input is $4, output $18 and cached input $0.40 per million tokens. Cache storage and grounding are billed separately. | 19 Feb 2026 | $2.00 | $12 | $0.20 | $4.50 | Baseline |
| Claude Opus 5.5Anthropic | 22 Sept 2026 | $4.00 | $20 | $0.20 | $8.00 | 78% more |
| GPT-5.6 SolOpenAIPrice before the GPT-6 launch, from OpenAI's announcement. OpenRouter now lists $2 / $10. | 9 Jul 2026 | $4.00 | $20 | – | $8.00 | 78% more |
| Claude Opus 5Anthropic | 24 Jul 2026 | $5.00 | $25 | $0.50 | $10 | 2.2× the price |
| Claude Fable 5Anthropic | 9 Jun 2026 | $10 | $50 | $1.00 | $20 | 4.4× the price |
| Claude Fable 5.1Anthropic | 1 Sept 2026 | $10 | $50 | $0.25 | $20 | 4.4× the price |
| GPT-6 AstraOpenAI | 4 Sept 2026 | $10 | $50 | $1.00 | $20 | 4.4× the price |
GPT-6.1 Sol and GPT-6 Sol rates were checked on 8 October 2026 against OpenAI model documentation. USD per million tokens, checked 2 Oct 2026 via OpenRouter. Comparison uses the blended price (3 input tokens for every output token). Haiku 5.5 and Sonnet 5.5 prices were updated from Anthropic's 7 October 2026 announcement. Gemini and Grok prices were checked against official Google and xAI documentation on 8 October 2026.
Official benchmark results
Reported by Google DeepMind on 19 Feb 2026 · exact values
Exact published scores · Higher is better. Unreported results are omitted.
| Benchmark | Gemini 3.1 Pro (high) | Gemini 3 Pro (high) | Claude Sonnet 4.6 (max) | Claude Opus 4.6 (max) | GPT-5.2 (xhigh) | GPT-5.3-Codex (xhigh) |
|---|---|---|---|---|---|---|
| Humanity's Last ExamAcademic reasoning (full set, text + MM) · No tools | 44.4% | 37.5% | 33.2% | 40% | 34.5% | – |
| Humanity's Last ExamAcademic reasoning (full set, text + MM) · Search (blocklist) + Code | 51.4% | 45.8% | 49% | 53.1% | 45.5% | – |
| ARC-AGI-2Abstract reasoning puzzles · ARC Prize Verified | 77.1% | 31.1% | 58.3% | 68.8% | 52.9% | – |
| GPQA DiamondScientific knowledge · No tools | 94.3% | 91.9% | 89.9% | 91.3% | 92.4% | – |
| Terminal-Bench 2.0Agentic terminal coding · Terminus-2 harness | 68.5% | 56.9% | 59.1% | 65.4% | 54% | 64.7% |
| Terminal-Bench 2.0Agentic terminal coding · Other best self-reported harness · (Codex) | – | – | – | – | 62.2% | 77.3% |
| SWE-Bench VerifiedAgentic coding · Single attempt | 80.6% | 76.2% | 79.6% | 80.8% | 80% | – |
| SWE-Bench Pro (Public)Diverse agentic coding tasks · Single attempt | 54.2% | 43.3% | – | – | 55.6% | 56.8% |
| LiveCodeBench ProCompetitive coding problems from Codeforces, ICPC, and IOI · Elo | 2887 Elo | 2439 Elo | – | – | 2393 Elo | – |
| SciCodeScientific research coding | 59% | 56% | 47% | 52% | 52% | – |
| APEX-AgentsLong horizon professional tasks | 33.5% | 18.4% | – | 29.8% | 23% | – |
| GDPval-AA EloExpert tasks | 1317 Elo | 1195 Elo | 1633 Elo | 1606 Elo | 1462 Elo | – |
| τ2-benchAgentic and tool use · Retail | 90.8% | 85.3% | 91.7% | 91.9% | 82% | – |
| τ2-benchAgentic and tool use · Telecom | 99.3% | 98% | 97.9% | 99.3% | 98.7% | – |
| MCP AtlasMulti-step workflows using MCP | 69.2% | 54.1% | 61.3% | 59.5% | 60.6% | – |
| BrowseCompAgentic search · Search + Python + Browse | 85.9% | 59.2% | 74.7% | 84% | 65.8% | – |
| MMMU-ProMultimodal understanding and reasoning · No tools | 80.5% | 81% | 74.5% | 73.9% | 79.5% | – |
| MMMLUMultilingual Q&A | 92.6% | 91.8% | 89.3% | 91.1% | 89.6% | – |
| MRCR v2 (8-needle)Long context performance · 128k (average) | 84.9% | 77% | 84.9% | 84% | 83.8% | – |
| MRCR v2 (8-needle)Long context performance · 1M (pointwise) | 26.3% | 26.3% | – | – | – | – |
View Google DeepMind's original charts
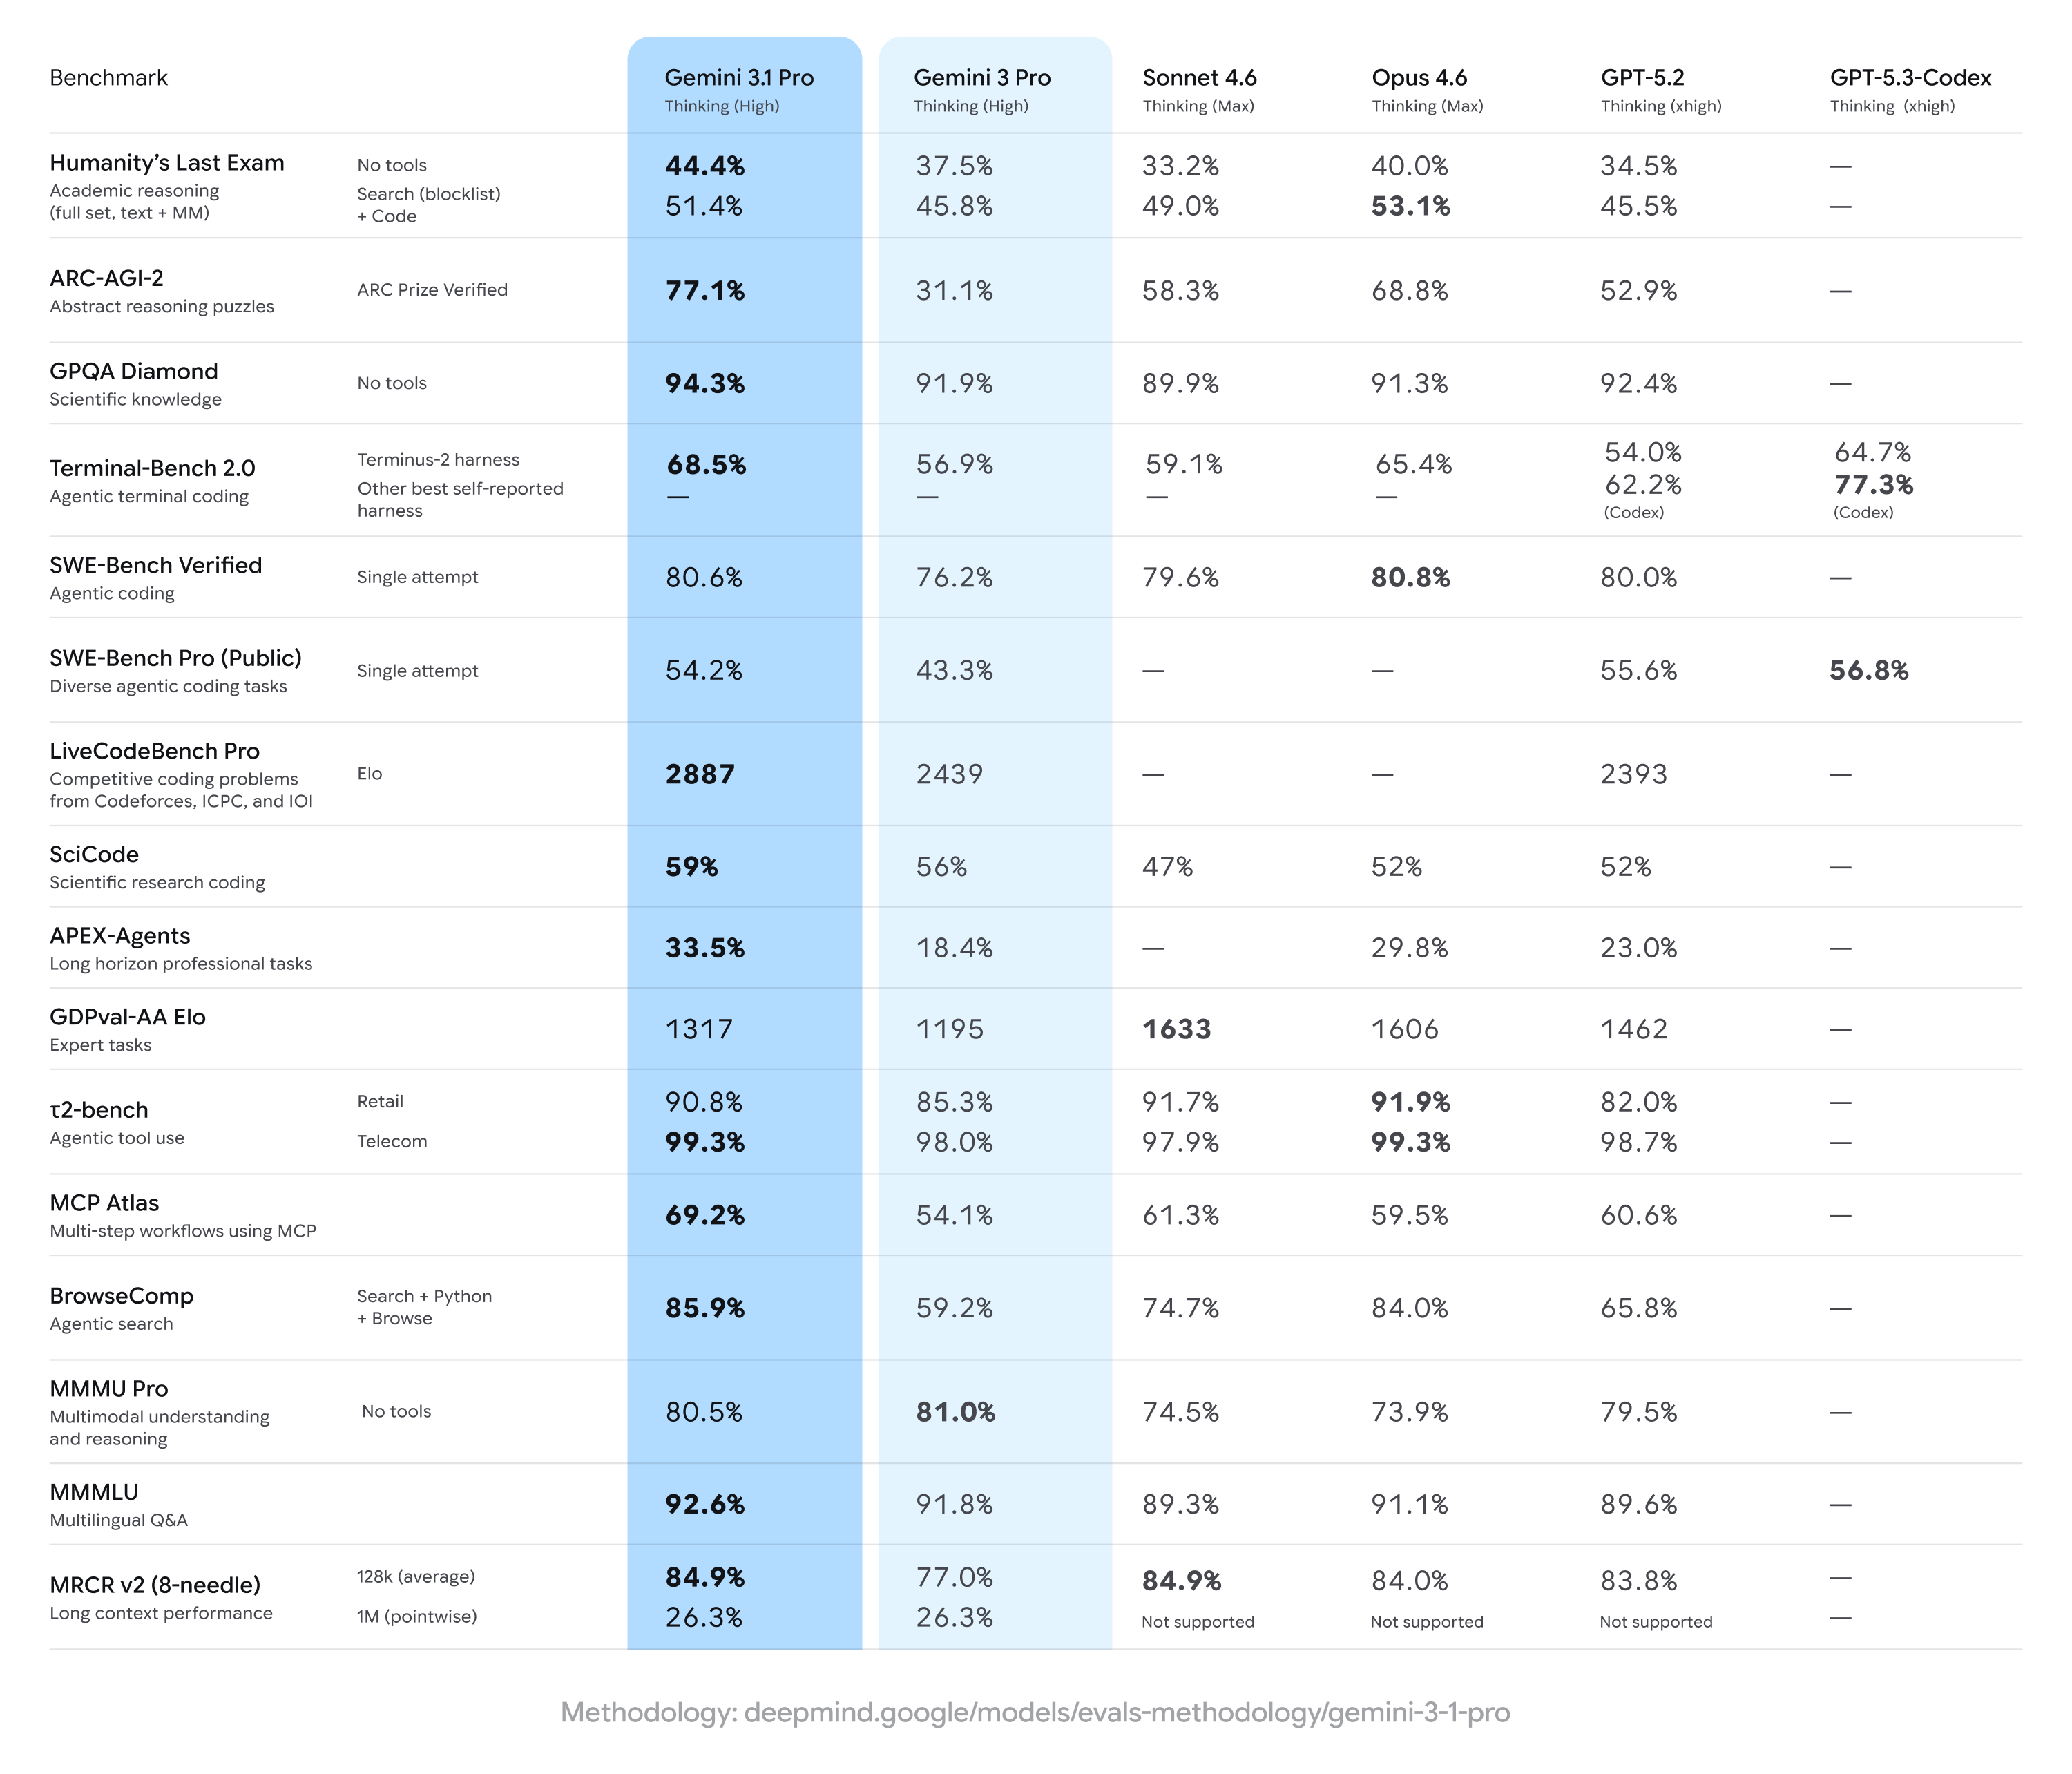
- Bold marks the best reported score in each row.
- Exact scores from the Google DeepMind model card. Gemini models use high thinking, Claude models use max thinking and GPT models use xhigh thinking.
- Terminal-Bench results using the Terminus-2 harness and the best self-reported Codex harness are separate rows. Do not combine them as one evaluation.
- Historical competitors are benchmark comparisons only. A dash means no published result or unsupported context length.